
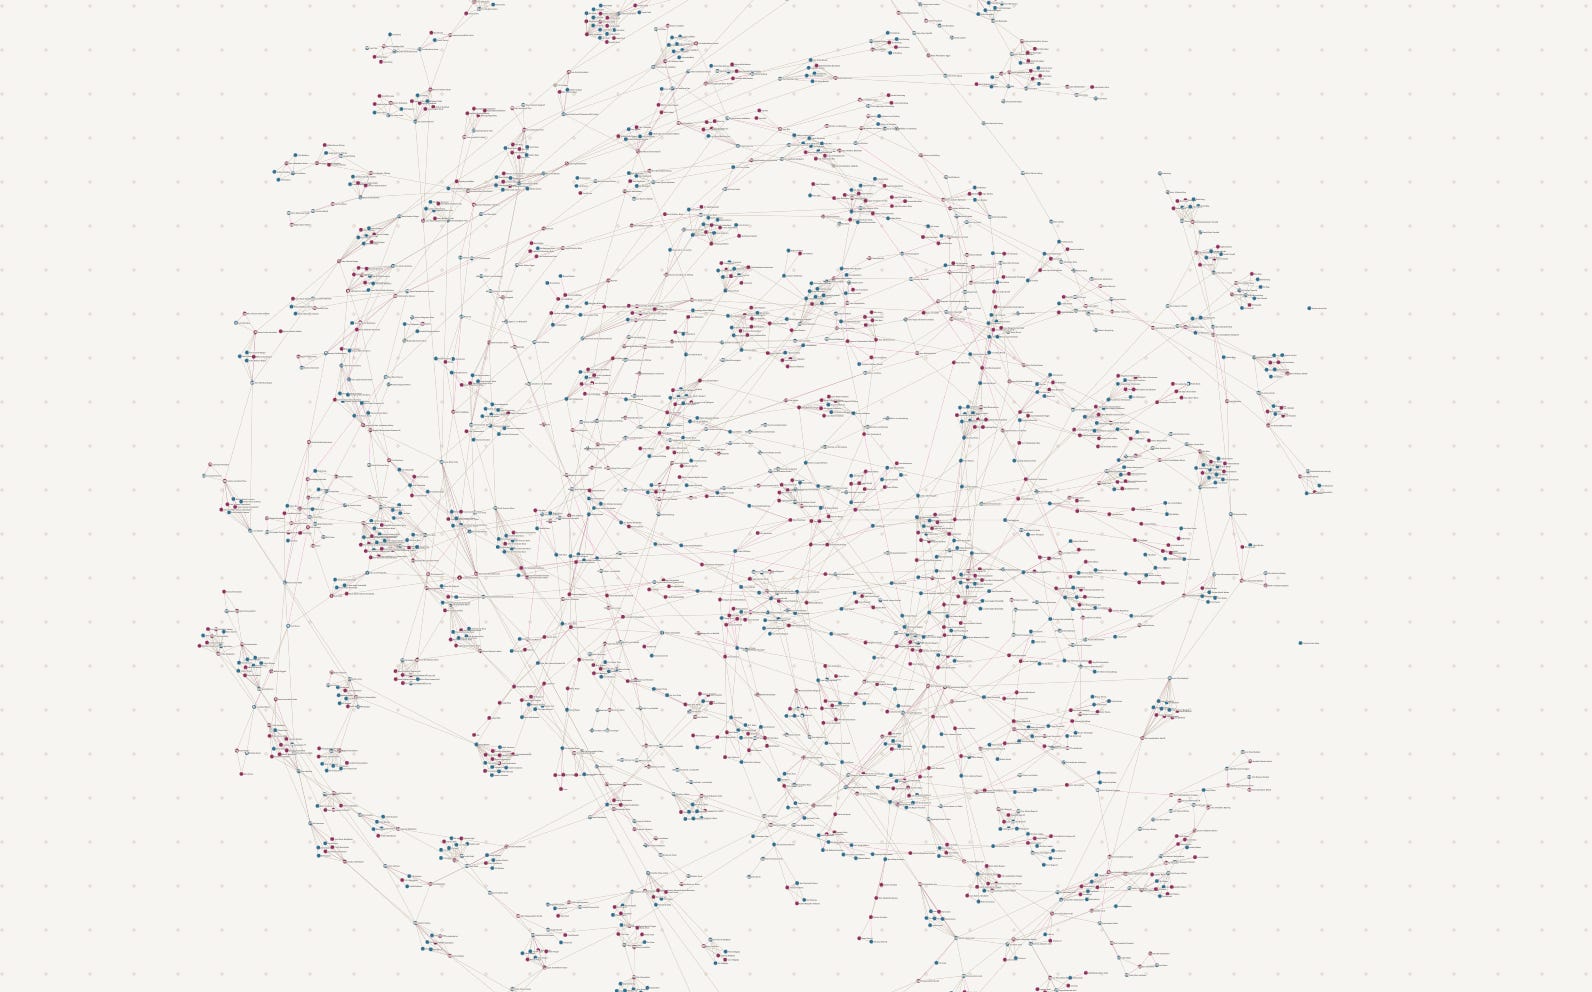
My previous article about LaTeX displayed one of my ten thousand hobbies. This article focuses on another of those hobbies, including a teeny tiny bit of LaTeX here too.
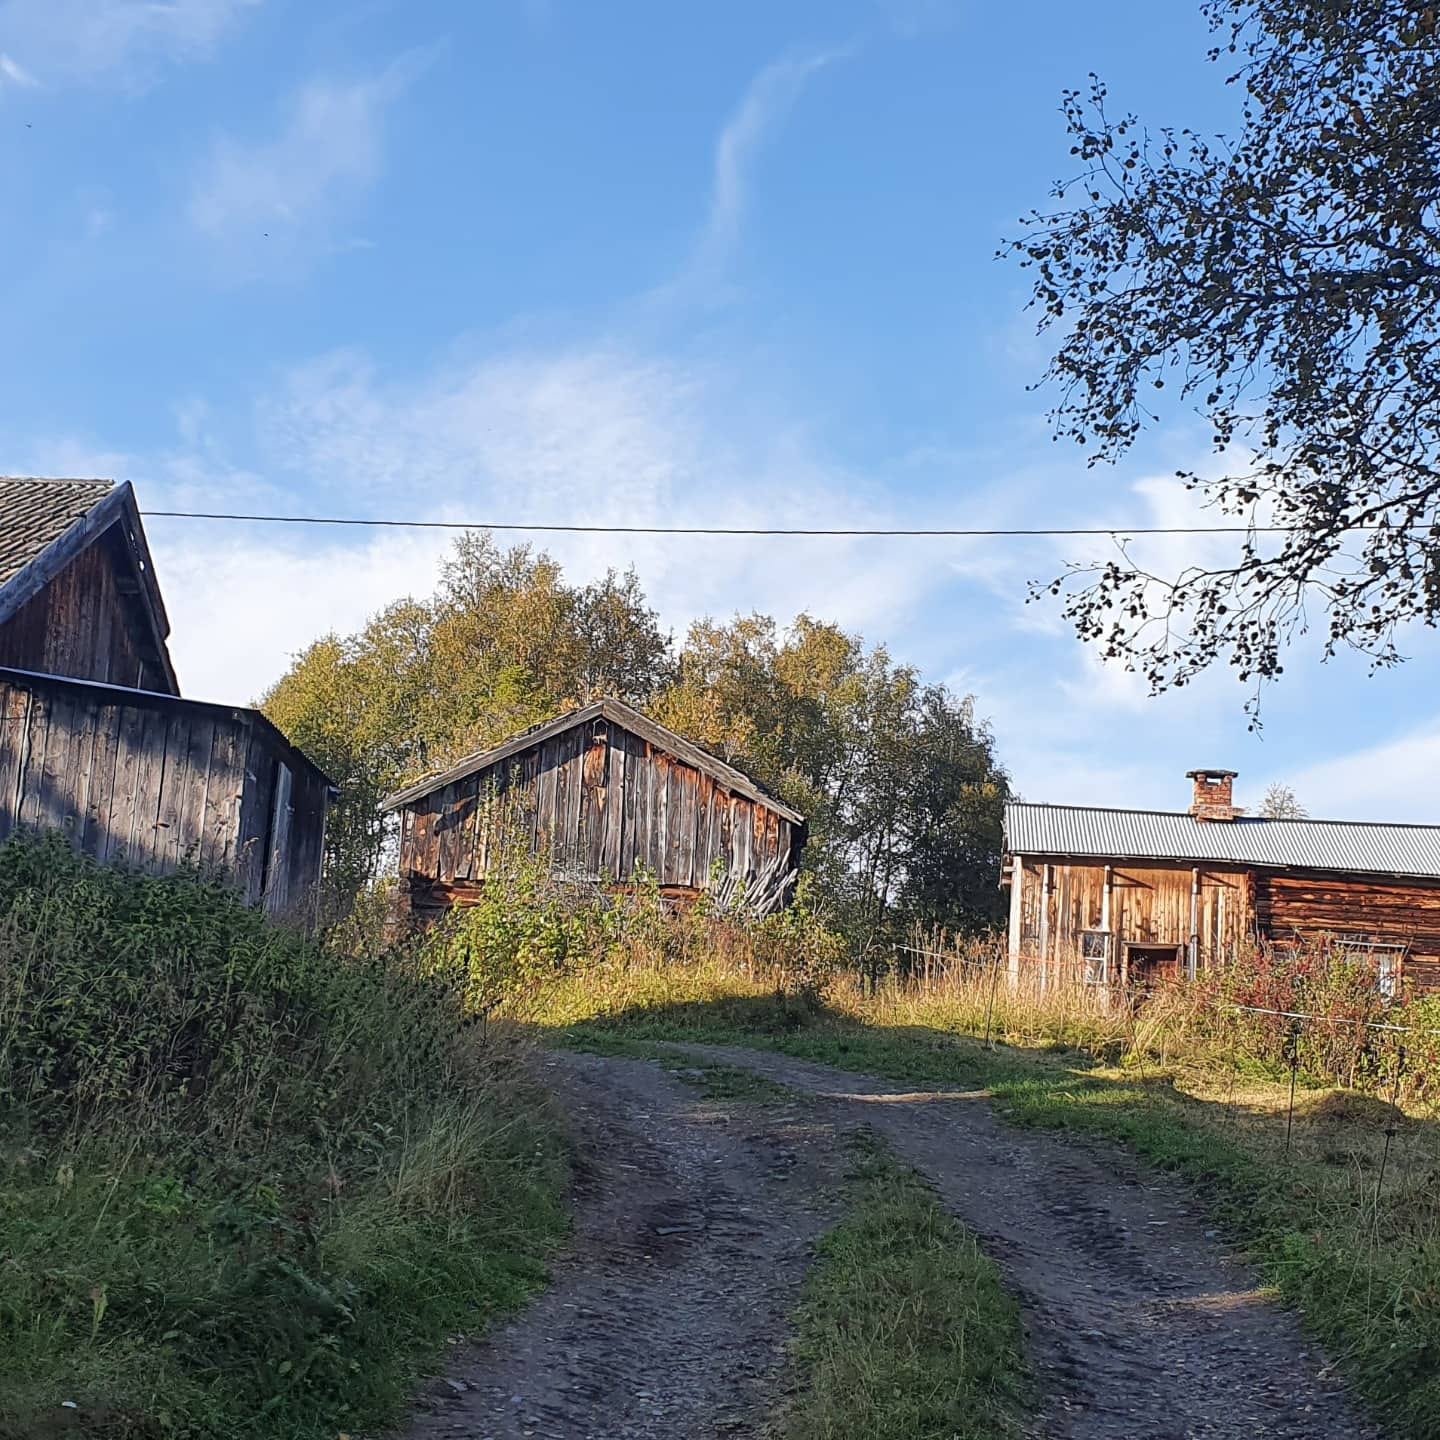
I’ve been interested in local history and genealogy for as long as I can remember. I grew up surrounded by traces of my ancestors at a tiny farm up in the Norwegian mountains. Where the eldest building has logs that’s more than 250 years old. 250 years is approx. 9 generations, and direct ancestry for nine generations are about a thousand persons. Who were they, those who chopped those logs down in the forest? Who were they, those who built the house? Who were they, those who lived there. Smiled there, laughed there, cried there, died there? How was their life, those who walked these same forests as I do today?
Questions like this intrigues me, and is much of the reason why I find this hobby fascinating. The other part of it is the discovery of information and knowledge. Having a few data points as a name, or a farm, a few dates and a child. And by that, being able to find them in a record, a church book, a tax list, in a newspaper, a passenger list. Puzzling together the pieces of forgotten lives. Feeling like Sherlock Holmes.
Anyways, I’ve tried all kinds of software to keep track of my genealogy research. I’ve tried open-source software, proprietary software, web-based solutions and desktop software. Every single time, I’ve returned to my pen and paper.
I have also build my own tools, but they were mere parsers between various formats. Once a GEDCOM-to-RDF-to-LaTeX parser as a hackathon-project in 2015. But they have never turned into something tangible. Now, however, with the help of AI, I’ve carpentered something I can actually use. And that my mother can use. And that you can use, if you want. The solution is deployed openly available on the web, it just contains a simple log-in solution to keep the ancestry trees separate. So you will have full control of your research, without being bothered by others. The rest of the article is about the implementation, and you’ll find more information about how you can use it at the end.
Why RDF?
A family isn’t necessarily straight forward to model. A person can have a biological father they never knew and a social father that they grew up with. The same ancestor can appear at several positions in a pedigree, because two branches married back together (the birds know this happens all the time in the countryside). Life events carry dates that are often approximate, sometimes just a year. There are several controlled vocabularies, as sex, partnership status, event types, kinds of parenthood, that I wanted to keep extensible per user need.
RDF handles this quite naturally, because it was designed for this open-world, endlessly-extensible data. Aneregister (my not so creative working name for this app) builds its model on schema.org where suitable terms of the things I need exists, like schema:Person, schema:givenName, schema:birthDate, etc. I’ve added a small vocabulary on top for the geanology-specific parts. A person serialised to RDF would look somewhat like this:
p:164 a schema:Person ;
  schema:givenName "Helge" ;
  schema:familyName "Gjermunsen" ;
  schema:birthDate "1752"^^xsd:gYear ;
  schema:deathDate "1825"^^xsd:gYear ;
  sl:farm pl:berg-holmestrand ;
  sl:kekule 164 ;
  schema:spouse p:165 ;
  sl:parentRelation
    [ sl:parent p:328 ;
      sl:role sl:role_far ;
      sl:relationType sl:parentrel_biologisk ;
      sl:primary true
    ] .
The parent relation points to a blank node, because it carries the kind of parenthood and a sl:primary flag marking which line the ahnetafel numbering follows. This makes it possible to switch between social parents and biological parents in the numbering system.
Sex, partnership status, event types and parent-relationship types are all skos:Concepts in named schemes, and users can add their own concepts that will travel with the data. It’s all triples!
The ahnetafel system
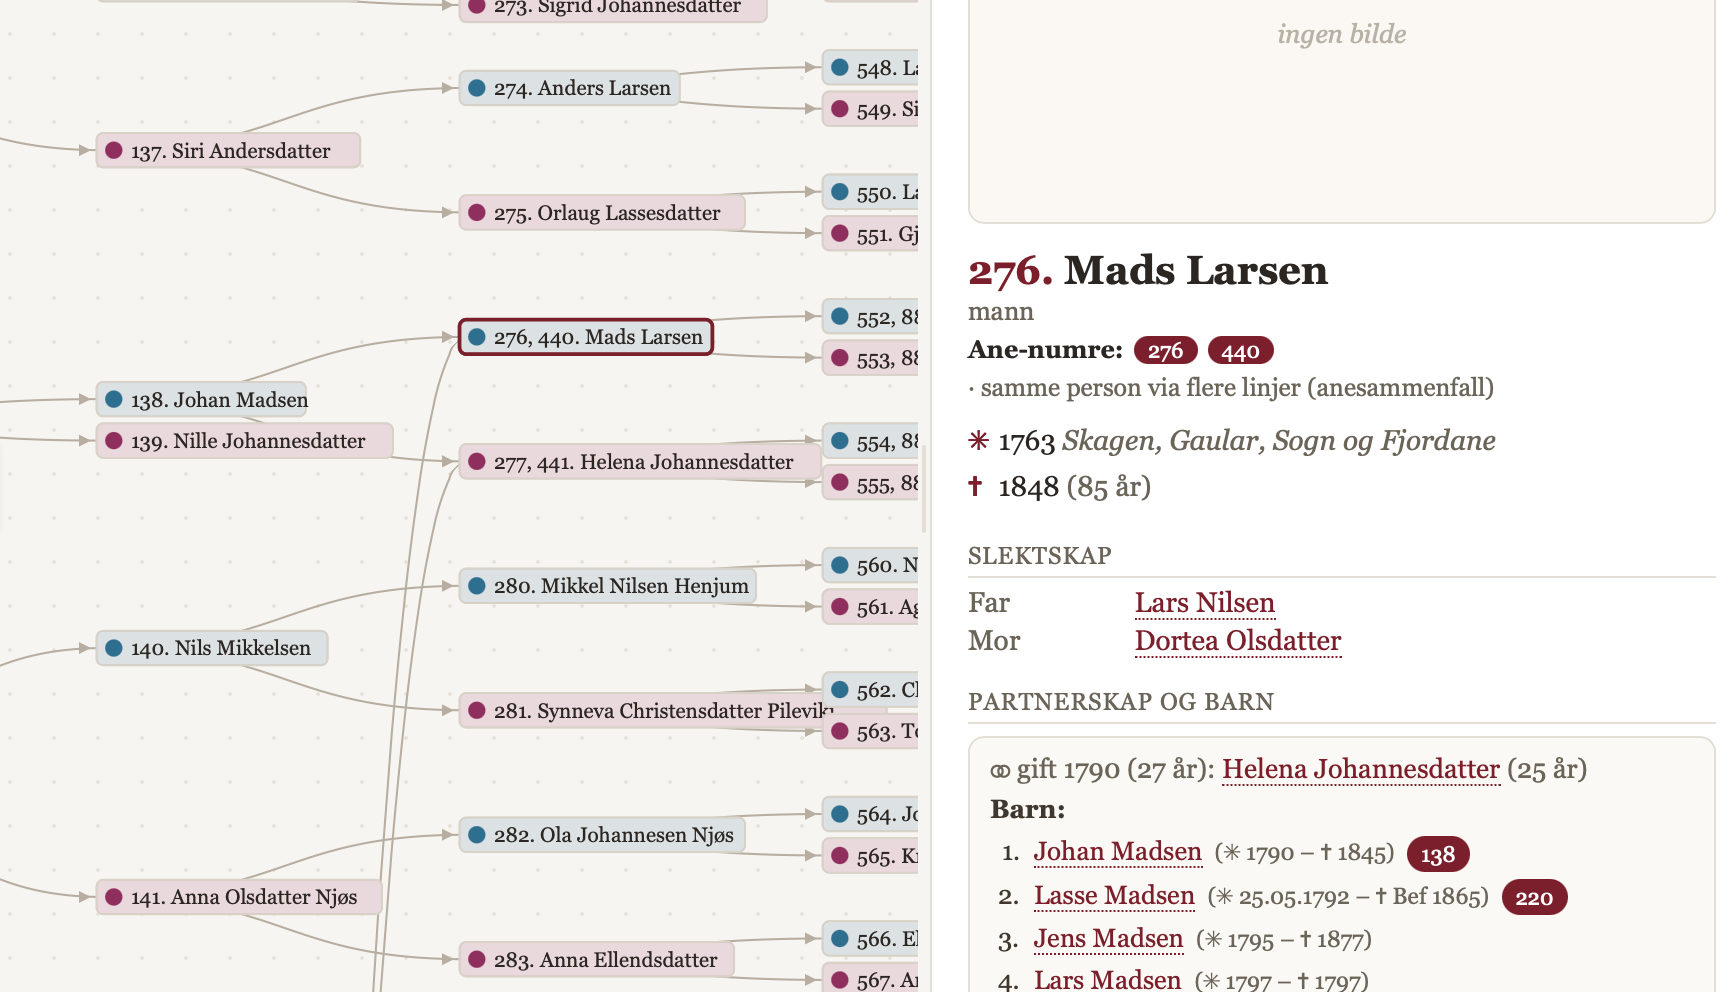
The ahnetafel system (sl:kekule value in the ontology) is an ancestor-numbering scheme made popular by the genealogist Stephan Kekulé von Stradonitz (and older still, going back to Eytzinger in 1590). The person at the center of the chart (the proband) is given the number 1. From any person n, the parents are found by:
father(n) = 2n
mother(n) = 2n + 1
So, the proband’s father is 2 and the mother is 3; the father’s parents are 4 and 5, the mother’s parents 6 and 7, and so on. Meaning, that the child of n is found at n/2. Aneregister lets you register a person by number, and it computes 329/2 = 164 to find the child that’s already registered. Since 329 is an odd number, that means it’s a female, and the mother of 164.
Since numbers are derived from position, a person can hold several ahnetafel numbers at once. When two branches marry back together, the same ancestor is reachable by more than one path, so a single node can be tagged with both 164 and 189. This is what we call pedigree collapse.
Pedigree collapse is the reduction of unique ancestors in a family tree. A single person node is simply referenced from several places in the ancestor graph, and the app can compute all the ahnetafel numbers a person occupies instead of representing them as different individuals in the data.
The app stores the lowest number as primary for stable sorting, but computes the whole set for display in the UI.
The back-end
The back-end of this application is a FastAPI service deployed on Fly.io that uses maplib as its knowledge graph engine. maplib is a Rust-powered, Python-native knowledge graph library that brings Polars DataFrames and Apache Arrow’s zero-copy columnar memory to RDF. In practice, that means the server gets a fast, dependency-light SPARQL engine.
from maplib import Model

m = Model()
m.read(pedigree_ttl, format="turtle")

# Count size of chart
count = m.query("""
  PREFIX schema: <https://schema.org/>
  SELECT (COUNT(?p) AS ?n) WHERE { ?p a schema:Person }
""")

# Who is the proband
proband = m.query("""
  PREFIX schema: <https://schema.org/>
  PREFIX sl:     <https://slekt.local/vocab#>
  SELECT ?g ?f WHERE {
    ?p sl:proband true .
    OPTIONAL { ?p schema:givenName ?g }
    OPTIONAL { ?p schema:familyName ?f }
  } LIMIT 1
""")
The server will store the RDF client users produce, and it reasons about that Turtle with SPARQL against the shared ontology (itself in RDF at /api/ontology). RDF serves as both the storage format, and the interchange format. With maplib, we can query huge graphs at blazing speeds in one-line, instead of hammering together some sub-system. The same engine produce the LaTeX-based “family book” PDF export, where SPARQL walk over the graph and feeds a geanologytree document.
Everything the app stores is standards-compliant RDF. Meaning, the same data could be validated with SHACL, enriched with SPARQL CONSTRUCT, or reasoned over with Datalog. All capabilities within maplib, by the way.
Import, export and sharing
The front-end uses N3.js to round-trip the entire memory model, ensuring lossless RDF import into the app.
For interoperability with the rest of the genealogy world, the app also speaks GEDCOM. And GEDCOM in the wild is like archaeology of encodings! It shows up as UTF-8, UTF-16 with a BOM, ANSEL, or Windows-1252. Getting special characters (know that I have plenty of æ, ø and å in my data) is a bit tricky. Importer reads raw buffer, discovers encoding, and decode accordingly, before mapping the record to the RDF triple model.
Sharing a person from your graph is a frozen RDF snapshot behind a public, read-only link, with no login required from the recipient. There’s, of course, an option to redact presumed living people before the snapshot leaves the server.
The front-end
Front-end development has never been my thing. I still write HTML the way Funky Chickens HTML Helper taught me in 1999. Good thing we got these language models to the rescue (or AI as some people call them). The front-end is a single index.html with d3.js for the visual layouts (graph, tree, pedigree, and fan-chart). Leaflet for maps, N3.js for RDF. It was grown feature by feature through natural-language conversation with my junior developer (my Claude instance).
Having a stable RDF data model reduce the amount of weird randomness such UI vibe-coding can result in. The schema is an explicit ontology linked with SKOS schemas, which works like a recipe for the AI-improvisation. No room for inventing things that aren’t in the schema.
Takeaways
Aneregister is a small app, but it solves all the things I missed in the numerous softwares I’ve tried before:
I have my ahnentafel numbering system
I have nice visualisations from many perspectives
I can find all inbreds (hø hø) 🪕
I have a stable RDF model with extensible schemas
I can add more than one chart without creating a new user (handy when doing genealogy research for friends)
I have connected national and global APIs for location register
I have connected the national digital archives for looking-up specific persons (pre-filled form)
I can export LaTeX PDFs ❤️
It’s free, and I can add whatever I like
If you would like to try it out, head over to https://rdfgen.fly.dev and have a look. It’s available in Norwegian and English, and requires logging in to ensure keeping your pedigrees to yourself.
About the author

Ontologist who code in C, Java and Python. Been a knowledge graph practitioner for over a decade, and had numerous talks on the topic around the globe. Knowledge Graph Specialist at Data Treehouse. Author of SHACL for the Practitioner and awarded amongst Norway’s Top 50 Women in Tech 2024.
This is quite usable and a fine application too. There are so many people building datasets based on genealogy, but the data is either purely personal, text based or institutional. Maybe you know of https://personsincontext.org/model# which is something like this but more formal. As an historian I would extend those schemas to capture more events, so that transactions, like sales, buying, inheritance and ownership, or goods can be included.
Nice 🪕 reference :)